1.0
Play
ParticipantInteractive scene generation
Explore a room-scale scene with your audience: ring the bell, unfold the map and get a response. Audiovisual generation continues, and your changes persist when you look away and return.
EVERWORLD
Real-time interactive spatial video models
Explore a scene, act on its objects and talk to its characters. Your input shapes what happens next.
INTERACTIVE ENTERTAINMENT
Audiences choose together, turning the story in a new direction.
Enter a role. Actions and dialogue change the next scene.
Versions
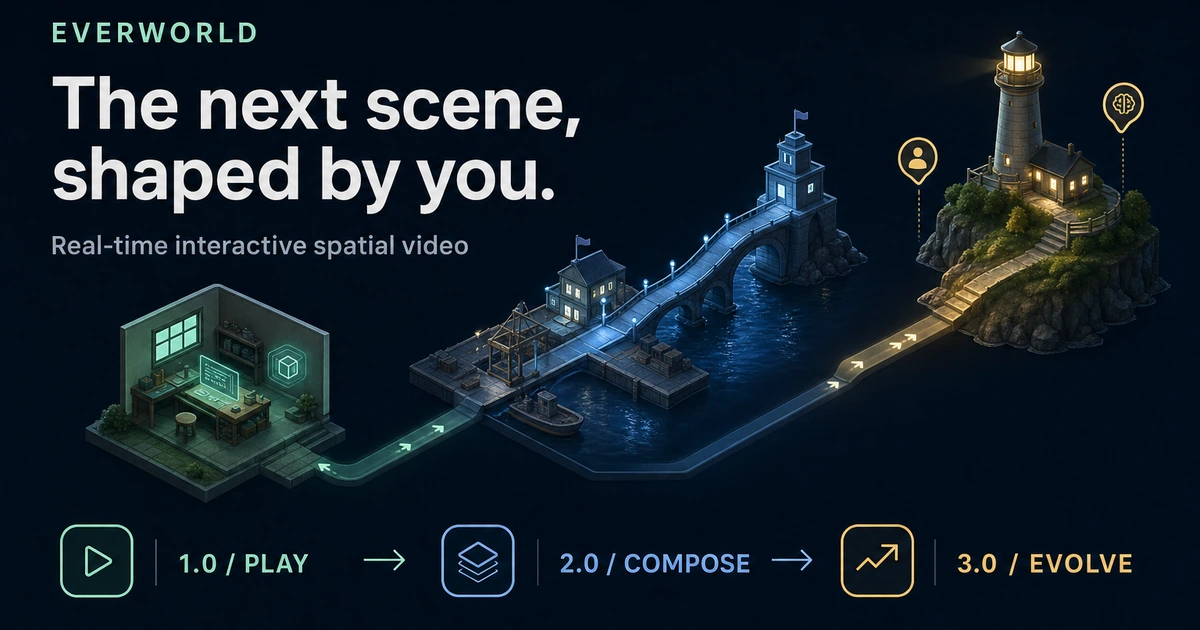
Explore a room-scale scene with your audience: ring the bell, unfold the map and get a response. Audiovisual generation continues, and your changes persist when you look away and return.
Describe a larger scene, then shape connected streets, docks and a lighthouse. Create interactive objects, edit the layout and rules, and step inside to try the space you designed.
Talk to your guide while exploring and change the route mid-conversation. Characters remember their experience, weigh possible actions and pursue their goals together as the scene evolves.
Architecture
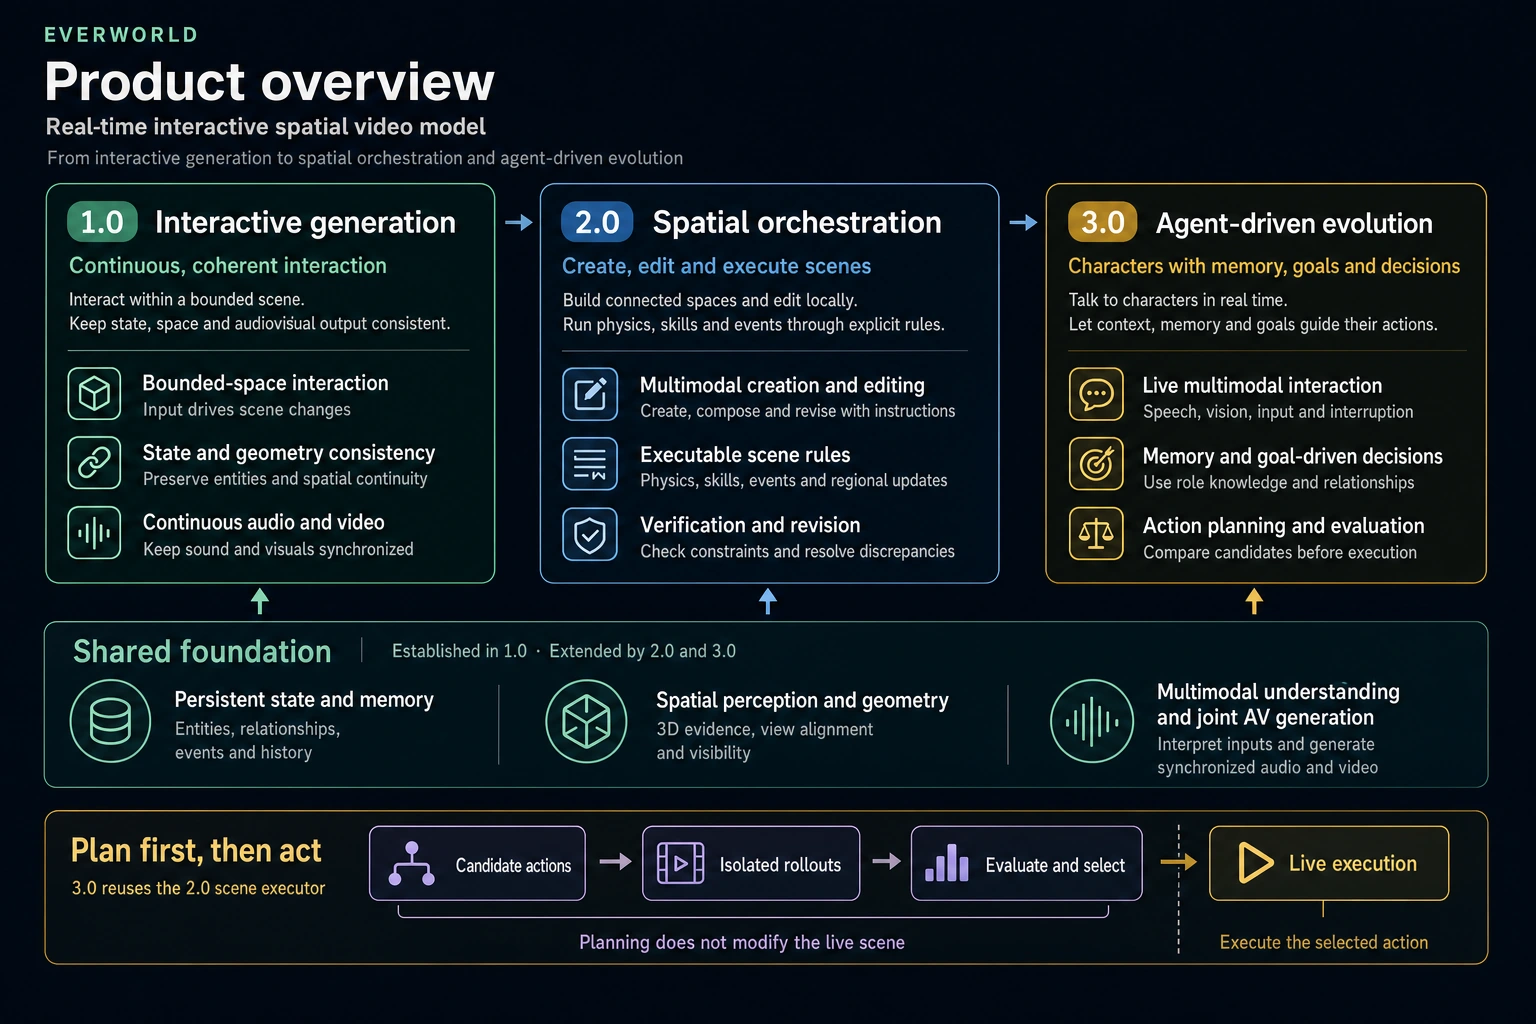
Continuous, coherent interaction
Interact within a bounded scene. Keep state, geometry, sound and visuals consistent as the scene changes.
Bounded-space interaction · State and geometry consistency · Continuous AVCreate, edit and execute scenes
Build connected spaces, edit locally and run physics, skills and events through explicit scene rules.
Multimodal creation · Executable rules · Verification and revisionCharacters with memory, goals and decisions
Talk to characters in real time. Their memory, goals and observations guide the actions they choose.
Live multimodal interaction · Role memory and goals · Action planningPersistent state and memory, spatial perception and geometry, multimodal understanding and joint AV generation. Established in 1.0 and extended by 2.0 and 3.0.
Candidate actions → isolated rollouts → evaluate and select → live execution. 3.0 reuses the 2.0 executor; planning does not modify the live scene.
Join us
Contribute to the models, runtime, evaluation or interactive experiences.
wenxiang@zju.edu.cn